AI detection performance
RAIDACL 2024
98.3%
accuracy on RAID
MGTDICAIE 2025
#1
AI detector on MGTD
Independent benchmarks show how well It’s AI detects AI-written text — and how often it falsely flags authentic human writing.
It’s AI’s performance is supported by published research and independent third-party benchmarking. Our MGTD results are reported in a peer-reviewed benchmark study, while our RAID result is listed on the official public leaderboard. Both evaluations measure English-language detection.
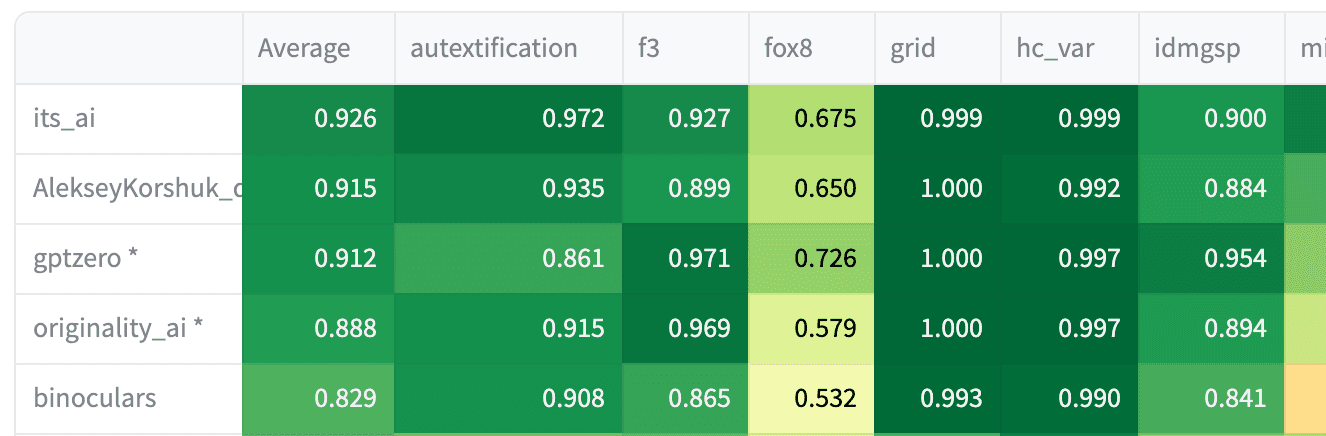
MGTD aggregates 15 benchmark datasets and nearly 2 million test samples into a direct comparison of leading AI detectors. It’s AI achieved the highest ROC-AUC, ahead of GPTZero, Originality AI, ZeroGPT and other evaluated systems.
RAID stress-tests AI detectors across LLMs, writing domains, decoding settings and adversarial modifications — including paraphrasing, misspellings, homoglyphs, whitespace attacks and other realistic perturbations.

Each benchmark links to the underlying paper, dataset or official benchmark page.
| Benchmark | What it tests | Samples | It’s AI result |
|---|---|---|---|
| MGTD Unified detector comparison | Cross-dataset detector comparison | ~2M samples | #1 Rank0.926 ROC-AUC |
| RAID Official public benchmark | Robust AI detection across models, domains and attacks | 600K+ test samples | 98.3% Accuracy |
| ASAP 2.0 Authentic student essays | Human-writing false positives | ~25K human texts | 0.8% FPR |
We report dataset-specific metrics rather than averaging benchmarks that measure different tasks.
Language-specific evaluations use the production detector configuration where applicable. Third-party benchmark and leaderboard results follow the benchmark’s published protocol.
Human-writing tests apply It’s AI’s product minimum of 200 characters when filtering is required, so texts the application itself would reject do not distort the reported false positive rate.
Accuracy is the proportion of correct classifications on datasets containing both human and AI texts. The false positive rate (FPR) measures how often authentic human text is incorrectly flagged as AI. ROC-AUC measures how well the detector distinguishes the two classes across decision thresholds.